InferOS: control your inference fleet
Deploy models, route requests and monitor your GPUs from one console. Run on NVIDIA and AMD, on-prem or in your cloud.
Private beta
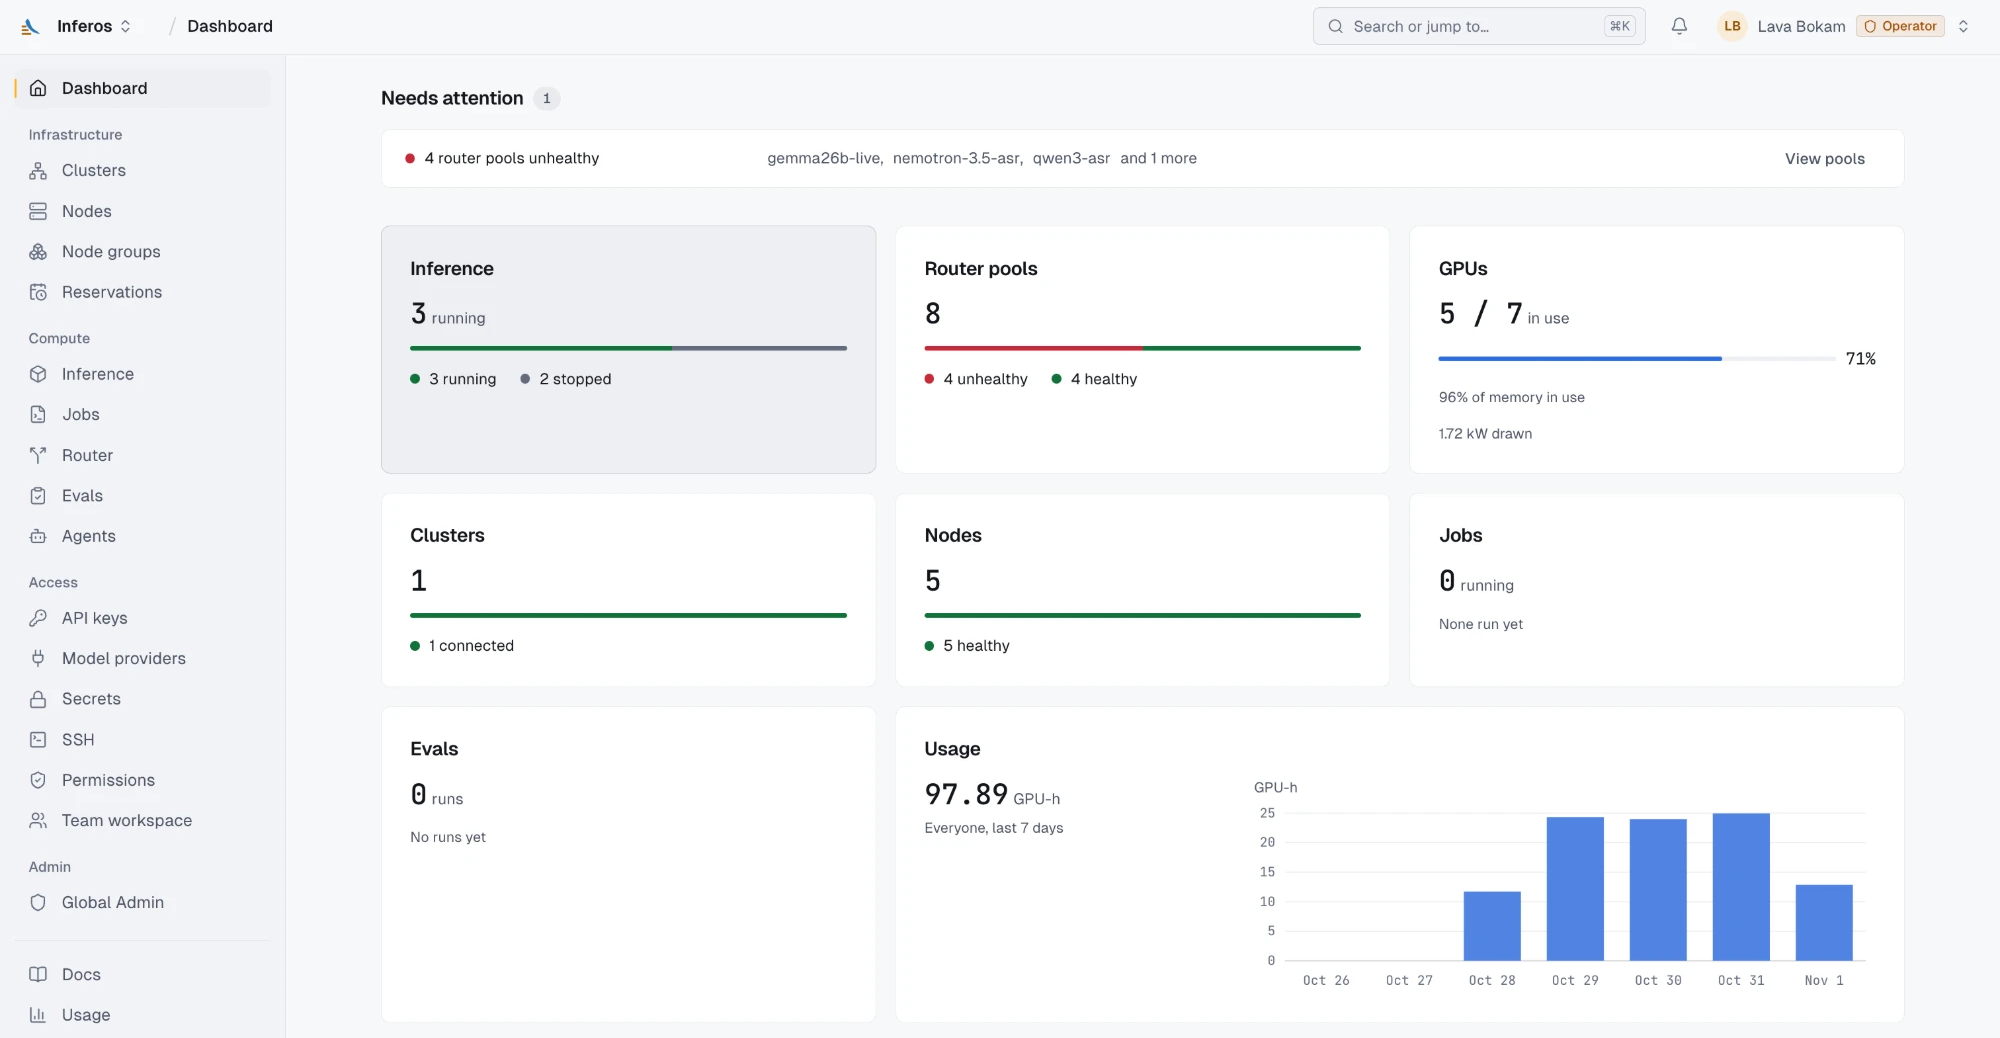
Operate the whole fleet
Manage infrastructure, model deployments and API traffic together. Keep hardware health, deployments and request usage in the same operational view.
- Clusters and nodes
- Enroll nodes with an agent, group them into clusters, and monitor GPU utilization, memory and health through Plow SMI.
- Model deployments
- Manage serving configurations, replicas and rollout history. Change capacity by adjusting replica counts.
- Request routing
- Route through one OpenAI-compatible endpoint with weights, latency budgets, capacity limits, circuit breakers and failover.
- Keys and usage
- Apply per-key policies, meter requests and manage role-based access. Sign in with Google or passkeys.
- Jobs and reservations
- Reserve GPUs, launch jobs from templates, follow their health and open SSH sessions to your nodes.
- Fleet evaluations
- Run evaluation suites against deployed models on the same hardware that serves them.
Deploy, route and observe
Model replicas are the unit you operate. InferOS connects their deployment, serving policies and telemetry.
Deploy models
Enroll your nodes and create a versioned model deployment. Choose serving configurations and replica counts.
Route requests
Send traffic through an OpenAI-compatible endpoint. Apply routing policies, latency budgets and capacity limits.
Observe the fleet
Track GPU health, model deployments and request usage. Run evaluations as you change models or configurations.
Your infrastructure, one control plane
Operate the GPUs you own or rent. Keep model serving and fleet management connected.
- NVIDIA and AMD
- Manage both vendors from the same console. Inspect GPU state and deployment health across the fleet.
- On-prem or in your cloud
- Run on your own nodes with a node agent. Contact us to discuss private-cloud and air-gapped deployments.
- Compiled serving with plow
- plow prepares and runs model plans. InferOS manages deployments, replicas, routing and usage around the engine.
See InferOS on your nodes
Bring your models, hardware and serving requirements.