The inference platform for GPUs you own
One platform to serve, route and meter models on NVIDIA, AMD or any accelerator.
- Runs on
- NVIDIA
- AMD
- Intel
- Apple silicon
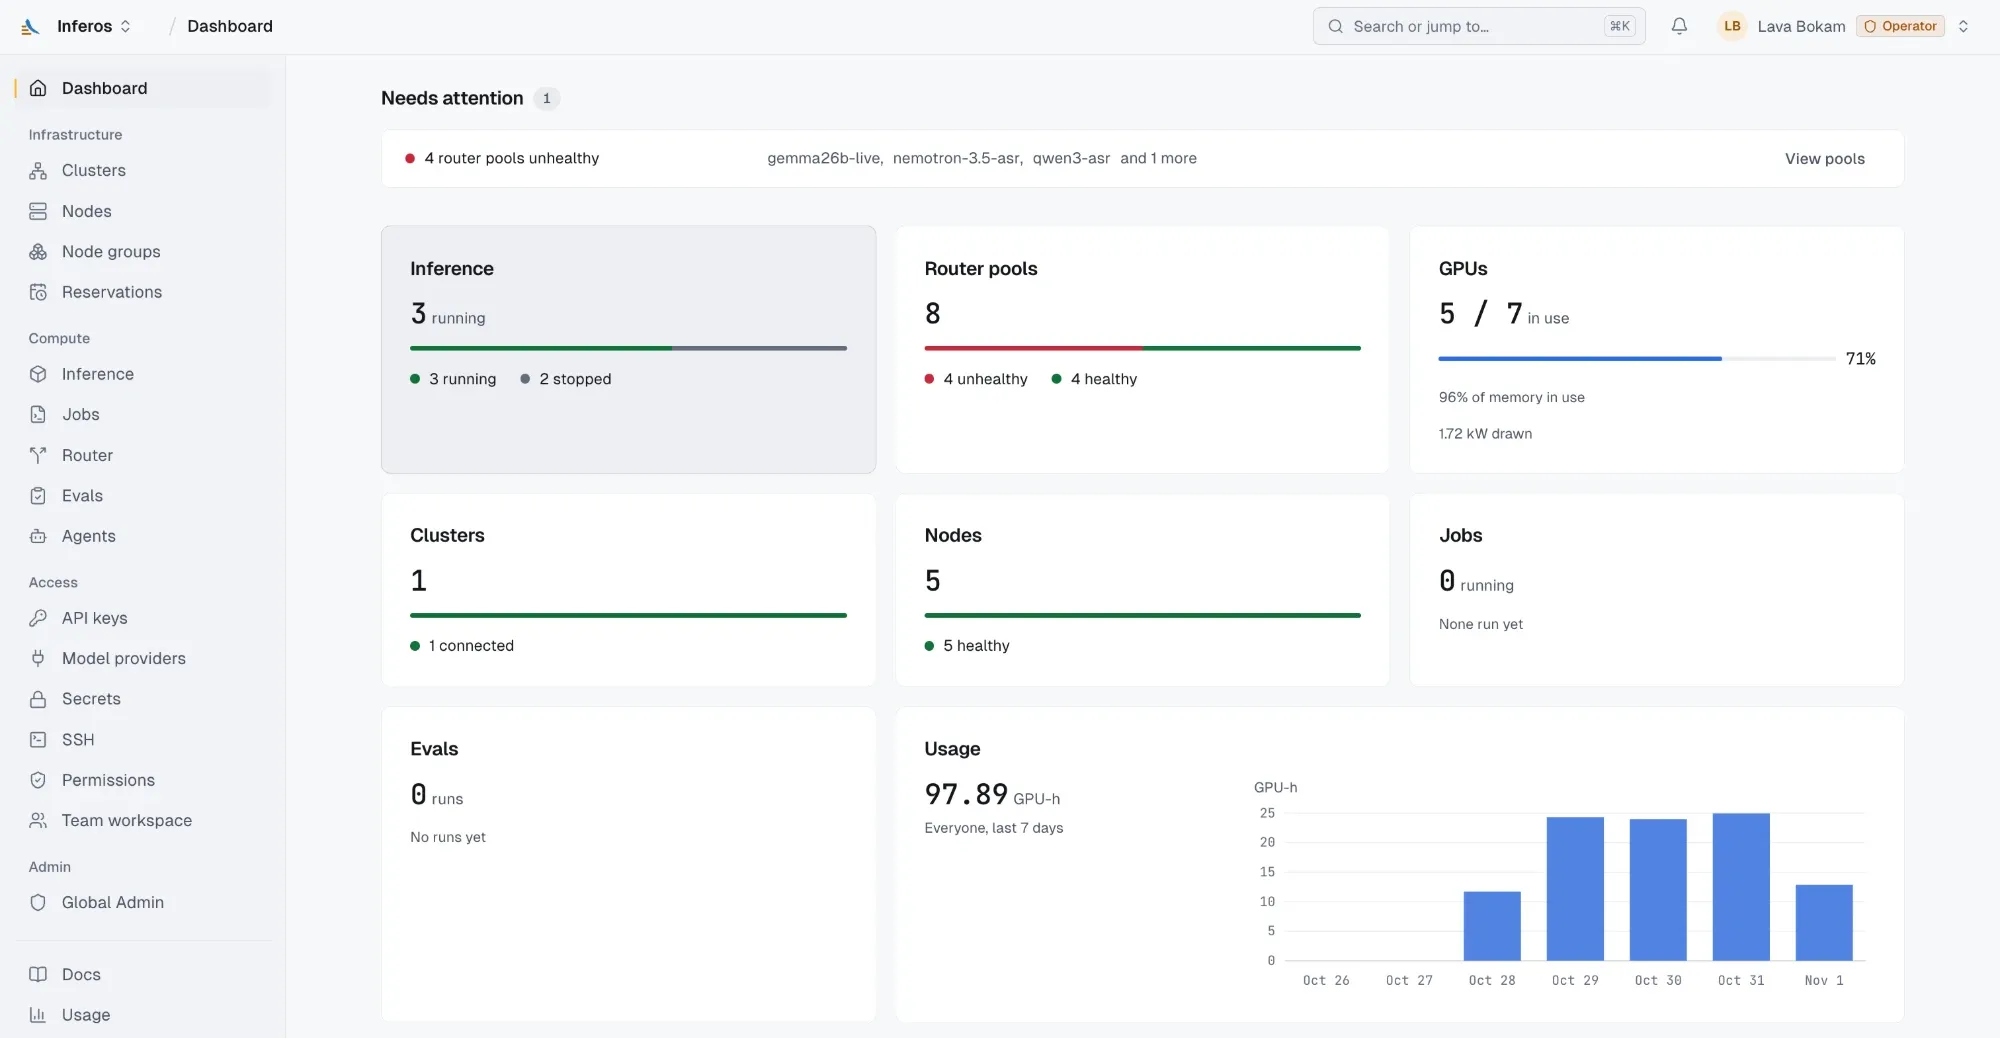
Four products, one platform
Use them together, or start with the open-source parts.
-
plow
The inference engine. Compiles each model ahead of time for your GPU, then serves it.
-
InferOS
The control plane. Runs your GPU machines as one managed inference platform.
-
Plow SMI
GPU monitoring. Live telemetry and power control for NVIDIA, AMD, Intel and Apple.
-
Model registry
Prebuilt models. Signed, prebuilt models that install with one command.
Everything between your GPUs and your apps
OpenAI-compatible, so apps switch with one line of code.
- Every request type
- Chat, embeddings, images, speech, realtime and video, through one API.
- Your GPUs and clouds
- Your own models next to OpenAI, Anthropic and Gemini, with your keys.
- Smart load balancing
- Routes by latency target and by which replica already holds the context.
- Built-in resilience
- Failover, circuit breakers and response caching on every route.
- Scoped API keys
- Model allowlists, expiry, rate limits and spend caps per key.
- Teams and tenants
- Accounts, invites, and plans with their own limits.
- Sign-in
- Google, email codes and passkeys.
- Usage per request
- Tokens and cost on every call, plus GPU hours, ready for chargeback.
- Dashboards and alerts
- Built-in metrics with latency alerts to Slack.
- Evals on live traffic
- Scheduled quality checks and model judges on the models you serve.
- Bring any machine
- One install script enrolls Linux machines with NVIDIA or AMD GPUs, or CPUs.
- Fit check first
- A model that won’t fit is refused before it can crash a GPU.
- Safe deployments
- Versioned revisions, warm-up checks, graceful drains and rollback.
- Planned capacity
- Scheduled scaling, GPU reservations and batch jobs.
- Engines you choose
- plow, vLLM and SGLang side by side.
Faster first words on the same GPUs
plow plans each model before it serves, so replies start sooner.
First token, typical
First token, slowest 1%
Each next token, typical
Fifty voice calls on one H100
Speech-to-text, the LLM and text-to-speech share one GPU.
Planned ahead of time
Each model compiles for its GPU, so start-up skips the warm-up.
Checked before it ships
Our own kernels, cuBLAS where it’s still faster, and an accuracy check on every result.
Built for teams serving their own models
Voice AI teams
Speech-to-text, the LLM and the voice on one GPU, with replies that start sooner.
Companies with private GPUs
Your models behind your firewall, with keys, limits and usage per team.
GPU clouds
Offer managed inference to your tenants on NVIDIA and AMD.
Teams without GPUs
Inference on dedicated GPUs we bring in, sized to your workloads and commitment.
Results, with every setting shown
- plow is open source: a compiler that emits packet streams NVIDIA and AMD
- The cold-start tax GH200, RTX PRO 6000
- Bringing up Kimi-K3 on day zero 8× MI355X
- Half the slope: long-context decode on 8× AMD MI350X 8× MI350X
- Measured on Blackwell: Gemma-4 decode vs vLLM RTX PRO 6000
Bring one model and one GPU
A 30-minute session with an engineer, on your models and hardware.